San Francisco Bay Area
Xuan LuAI Infrastructure Engineer
Building the systems behind AI.
I work on large-scale LLM inference at AWS SageMaker HyperPod, focusing on distributed serving, Kubernetes, performance and reliability.
About Me
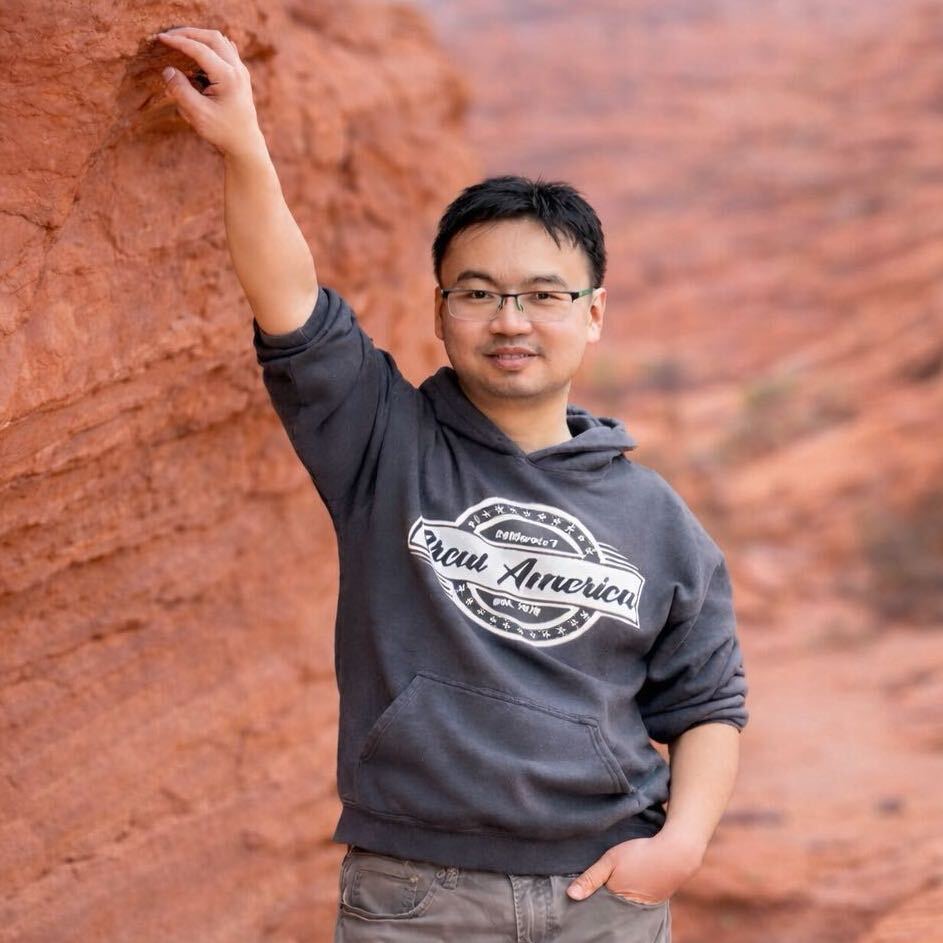
I’m an AI infrastructure engineer based in the San Francisco Bay Area. I approach engineering through practical systems design: understand the bottleneck, test assumptions and verify how a system behaves in production.
At Amazon, my work has spanned customer-facing software, machine learning serving platforms and now large-scale LLM inference at AWS SageMaker HyperPod. I’m interested in the questions that appear when a model becomes a service: how requests share GPUs, where latency comes from and how the system stays reliable under load.
Outside engineering, I write about AI and learning, and use AI to make short films and music. I like turning an idea into something people can read, watch or try. The aim is to make room for more interesting work—and more life outside it.
Get in touchWhat I work on
More about my workDistributed LLM inference
Serving models across GPU infrastructure, including prefill/decode disaggregation and request routing. I focus on how the pieces fit together and the tradeoffs between responsiveness, throughput and resource use.
KV cache & performance
Understanding how cached state moves between GPUs, memory and storage, and when reuse helps. Benchmarking and load testing turn an architectural idea into evidence about latency and throughput.
Kubernetes & operations
Building operators and deployment workflows that make inference easier to run. This includes workload lifecycle management, scaling, observability and diagnosing failures in production.